

Qwen API: Alibaba Direct vs a Gateway
Qwen API from Alibaba Model Studio direct vs an OpenAI-compatible gateway: regional keys and endpoints, workspaces, default thinking and enable_thinking.
By OceanToken Team
Editor's note: We run a gateway, so weigh our view accordingly. If Qwen is one of several model families in your product, a gateway is the simpler default. If you need a specific region, a known data location or Alibaba's native thinking switches on day one, go to Alibaba. The decision rarely comes down to the model itself. It comes down to which region, which key and which parameters actually reach it.
Short answer: For a Qwen API gateway versus Alibaba direct: Alibaba Cloud Model Studio is the publisher's own API, with six regions, per-region keys and native switches such as enable_thinking. An OpenAI-compatible gateway such as OceanToken serves qwen/qwen3.8-max-0902 and qwen/qwen3.8-flash next to other model families on one key. Pick Alibaba for region control, a gateway for a multi-model product.
Alibaba direct vs a gateway, side by side
Values come from Alibaba's Model Studio docs and our own Qwen pages on November 9, 2026.
| Alibaba Model Studio direct | OceanToken gateway | |
|---|---|---|
| Model ids | qwen3.8-max, qwen3.8-flash and others, per region |
qwen/qwen3.8-max-0902, qwen/qwen3.8-flash |
| Base URL | Workspace domain such as https://{WorkspaceId}.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1 |
https://api.oceantoken.ai/v1 |
| Keys | One per region; not usable across regions | One key |
| Thinking controls | enable_thinking, thinking_budget via extra_body |
reasoning_effort listed on the model page |
| Context and output | See the model list for your region | 984K tokens context, up to 131K output |
| Other model families on the same key | Some, such as DeepSeek, per Alibaba's regions page | DeepSeek, GLM, Kimi, Claude, GPT, Gemini |
Regions, keys and endpoints on Alibaba
Alibaba's regions page lists six Model Studio regions: China (Beijing), Singapore, Germany (Frankfurt), Japan (Tokyo), China (Hong Kong) and US (Virginia). The line that matters most is short: each region has its own endpoint, API key and model list, and these cannot be used across regions.
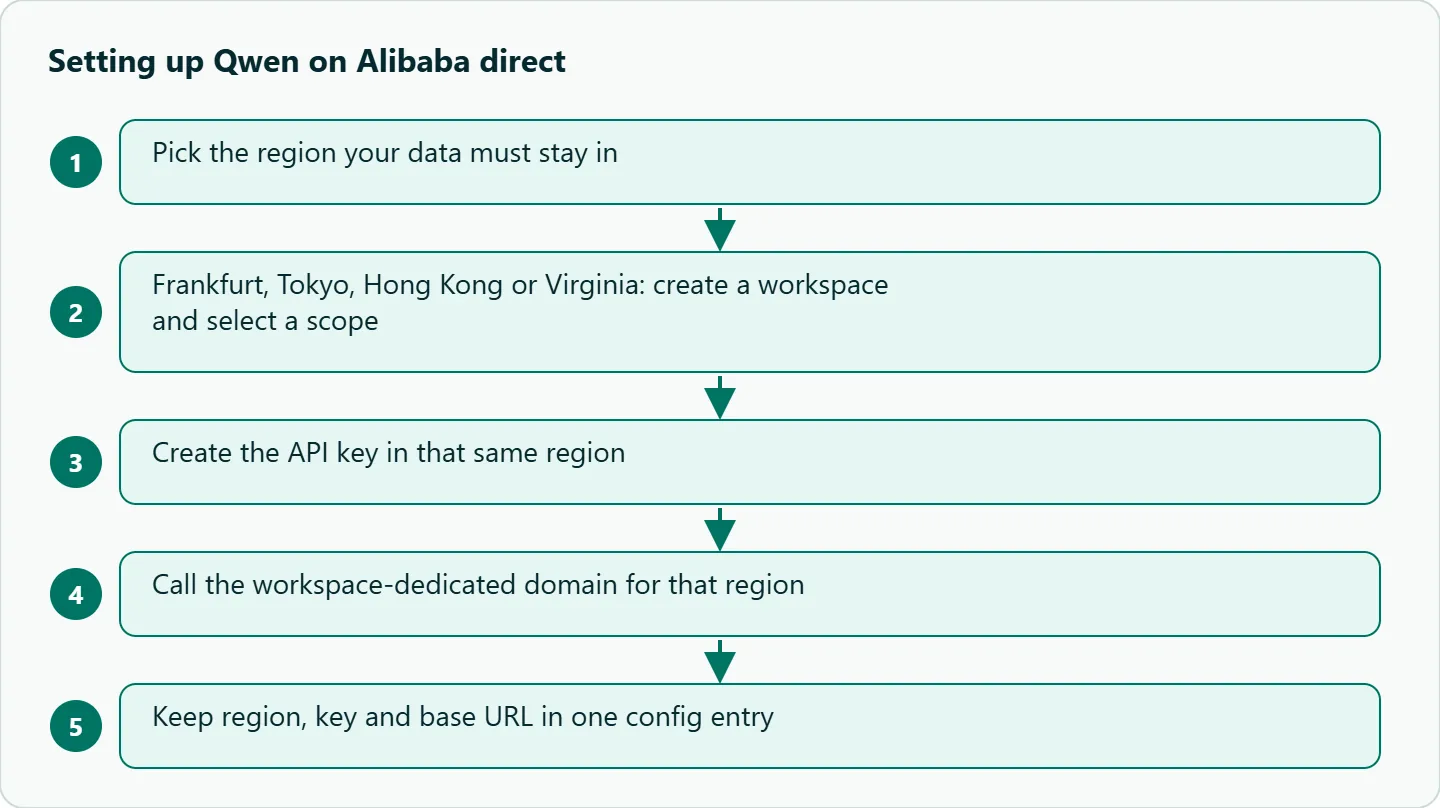
That produces the classic first-day failure. Someone creates a key in Singapore, copies a Beijing URL from an example, and gets an authentication error that looks like a bad key. The key is fine; it belongs to a different region. Keep the region, the key and the base URL together in one config entry so they can't drift apart.
Four regions add a step. Frankfurt, Tokyo, Hong Kong and Virginia use workspaces to separate deployment scopes, so you create a workspace and select a scope before the first call. The page also recommends the workspace-dedicated domain, {WorkspaceId}.{region}.maas.aliyuncs.com, and says the older DashScope domain no longer gets new features after September 30, 2026. If your code still points at a DashScope URL, migrating means replacing the domain in the request URL.
The upside of all this configuration is control. Alibaba says the region determines the access point and data storage location, the deployment scope determines where inference runs, and request data is stored in that region. If a customer contract names a processing location, that is a strong reason to go direct.
Thinking is on by default for Qwen3.8
The second difference costs money quietly. Alibaba's deep thinking docs say the Qwen3.8 hybrids, including qwen3.8-max, qwen3.8-flash and qwen3.8-27b, have thinking mode enabled by default, while qwen-plus and qwen-flash do not. Thinking content is billed as output tokens, and the reasoning comes back in reasoning_content with the answer in content.
On Alibaba you turn it off with enable_thinking: false, and you can cap it with thinking_budget. Both are non-standard parameters, so with the OpenAI Python SDK they go in extra_body. Code that worked on an older Qwen tier without thinking can therefore get slower and more expensive after a model-id change, with no error to tell you why.
Through a gateway the question is whether that switch arrives. Our Qwen3.8 Max model page lists reasoning_effort, tool_choice and response_format; it doesn't list enable_thinking. Our text guide says a parameter the model does not support is dropped and the request runs without it, so a successful response doesn't prove the setting took effect. Don't assume either way. Check with the script below before you rely on it.
Open weights, different hosts
Some Qwen sizes are released as open weights, so they can be self-hosted or served by third-party hosts, and those deployments don't all publish the same details, such as numeric precision or context length. The same prompt can pass strict JSON validation on one route and fail on another, and a difference in how the model is served is one plausible cause. Treat that as a hypothesis to test with your own eval, not a known fact about any host.
Self-hosting gives you full control of data location and fine-tuning, at the price of running the servers. If you depend on strict JSON or long agent loops on any route, keep one route fixed while you evaluate and rerun a small eval whenever you change it.
Same code, two bases
This script asks one question: does each route respect your thinking setting? It sends the same short prompt to each route you have a key for and prints completion tokens and whether reasoning came back.
import os
from openai import OpenAI

TARGETS = {
    # Alibaba direct: use the workspace domain and region where your key was created
    "alibaba": (os.getenv("ALIBABA_BASE_URL", ""), "qwen3.8-flash", "DASHSCOPE_API_KEY",
                {"extra_body": {"enable_thinking": False}}),
    "oceantoken": ("https://api.oceantoken.ai/v1", "qwen/qwen3.8-flash", "OCEANTOKEN_API_KEY",
                   {"reasoning_effort": "low"}),
}
for name, (base, model, env, opts) in TARGETS.items():
    if not base or env not in os.environ:
        continue
    r = OpenAI(base_url=base, api_key=os.environ[env]).chat.completions.create(
        model=model, max_tokens=800,
        messages=[{"role": "user", "content": "Reply with the number only: 12*12"}], **opts)
    m = r.choices[0].message
    print(name, r.usage.completion_tokens, bool(getattr(m, "reasoning_content", None)))
A one-word answer should need only a handful of completion tokens. If a route returns hundreds of them, or a non-empty reasoning_content, your setting isn't reaching the model on that route. Run it again with thinking on (drop the option) to see the difference; if the counts barely move, the switch isn't being applied.
Qwen API gateway or Alibaba direct: our pick
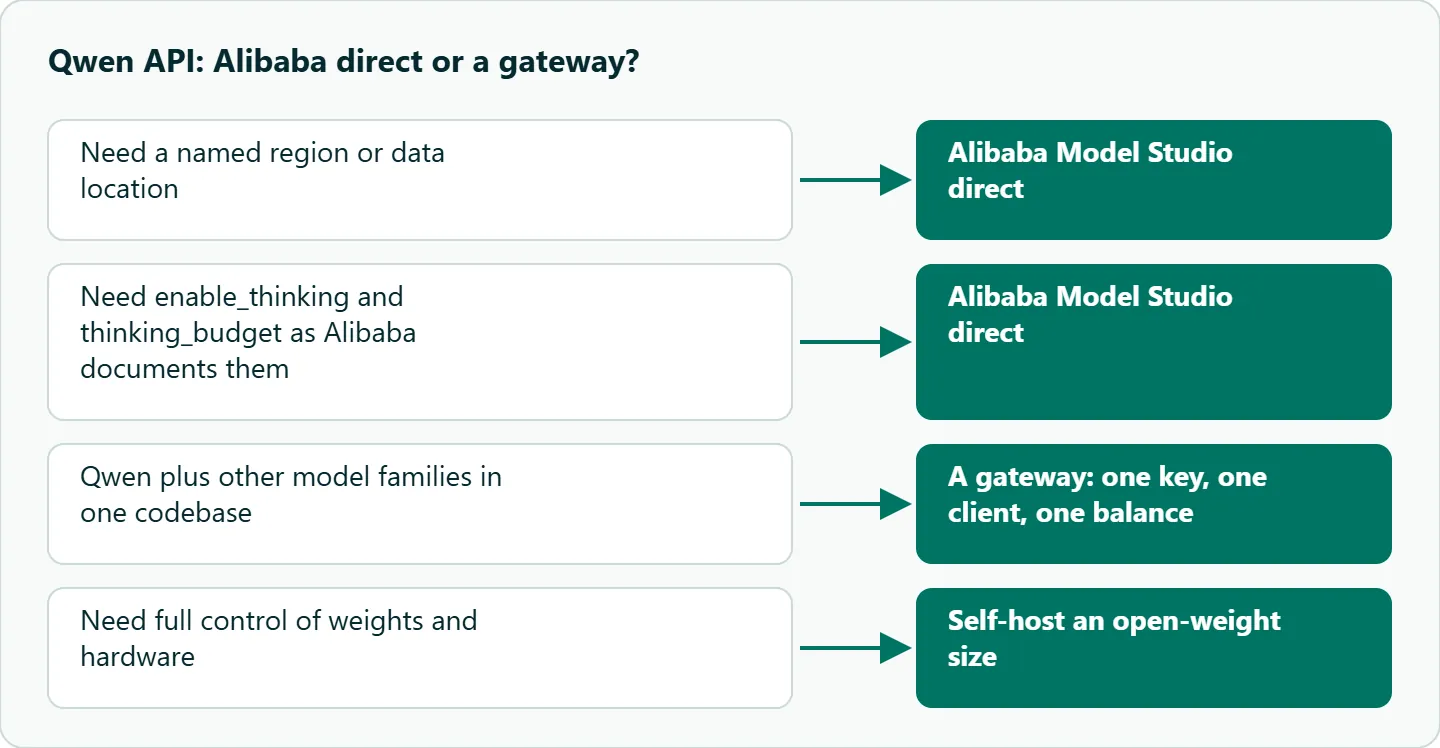
- Need a named region or data location? Alibaba direct, because the region sets where requests are stored and where inference runs.
- Need
enable_thinkingandthinking_budgetexactly as Alibaba documents them? Alibaba direct, because those are the publisher's own parameters. - Qwen plus Claude, DeepSeek or GLM in one codebase? A gateway, because you keep one key, one client and one balance, and switching models is a model id change.
- Need full control of weights and hardware? Self-host an open-weight size and accept the operations work.
Our take: For a multi-model product, default to OceanToken with qwen/qwen3.8-flash and move up to qwen/qwen3.8-max-0902 where your eval shows a quality gap. That doesn't remove the two failure cases above, a thinking setting that never arrives and a key used in the wrong region on the direct side, so run the script on both routes and keep Alibaba direct set up as a tested fallback. When a result looks off elsewhere, the publisher's endpoint shows you what Qwen itself does.
How to test this on your workload
- Pick 20 of your real prompts, including a few that need a strict output format.
- Send them to Alibaba in your region and to a gateway, both on
qwen3.8-flash. - Compare answer agreement, p50 and p95 latency, and completion tokens.
- Repeat with thinking off on each route and confirm that completion tokens drop.
Running it on OceanToken
Use base URL https://api.oceantoken.ai/v1 with qwen/qwen3.8-flash, or qwen/qwen3.8-max-0902 for the larger model (Qwen3.8 Max model page). What that gives you, per our /qwen-api page checked 2026-11-09:
- One key for Qwen and other families. The same key reaches DeepSeek, GLM, Kimi, Claude, GPT and Gemini, so comparing Qwen against another family is a one-string change.
- OpenAI-compatible, with the Anthropic Messages format too. You change the base URL, key and model id and keep your SDK code; there is no per-region key to manage.
- Prepaid, no subscription. You top up a USD balance, purchased credits last 12 months, and the page says failed requests are free.
See the current rate on /qwen-api. For a working tool loop on these ids, see our Qwen function calling in Python guide.
FAQ
Why does my Alibaba key fail in another region? Keys, endpoints and model lists are regional and can't be used across regions. Create a key in the region whose URL you call.
Do Qwen3.8 models think by default? On Alibaba, yes: the Qwen3.8 hybrids have thinking enabled by default, and thinking tokens bill as output. Turn it off with enable_thinking: false in extra_body.
Does a gateway forward enable_thinking? Don't assume it. Our model page lists reasoning_effort rather than enable_thinking, and unsupported parameters are dropped without an error, so test with the script above.
Do I still need the DashScope domain? Alibaba recommends the workspace-dedicated domain and says the DashScope domain gets no new features after September 30, 2026.
Can I switch routes without code changes? Mostly. The base URL, key and model id change, and you should re-test any parameter you rely on.
Sources
- Alibaba Cloud Model Studio: regions (checked 2026-11-09)
- Alibaba Cloud Model Studio: deep thinking (checked 2026-11-09)
- Alibaba Cloud Model Studio: OpenAI compatibility (checked 2026-11-09)
- OceanToken docs: text generation (checked 2026-11-09)
- OceanToken Qwen API page (checked 2026-11-09)
- OceanToken Qwen3.8 Max model page (checked 2026-11-09)
Get your OceanToken API key
- Create an OceanToken account and an API key.
- Copy the snippet below, paste your key, and run it.
- Check the current rate on /qwen-api.
curl https://api.oceantoken.ai/v1/chat/completions \
  -H "Authorization: Bearer $OCEANTOKEN_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model": "qwen/qwen3.8-flash", "messages": [{"role": "user", "content": "Hello"}]}'
More from the blog
Seedance 2.5 vs Wan 3.0 Prime by Job
Seedance 2.5 vs Wan 3.0 Prime for API video: what each call can hold, how each is billed, and which jobs to send to which model, with ids and code.
Seedance vs Veo 3.1 for 1080p, by Shot
Seedance vs Veo 3.1 for 1080p: when Seedance 2.0 Upscaled is enough, when to render native on Seedance 2.5 or Veo 3.1, and the model ids for each shot.
Official Kling API vs a Multi-Model Gateway
Official Kling API or a multi-model gateway? Kling versions, keys, concurrency and result links compared, plus a simple rule for which route fits your product.